
ServiceNow AutoSynthData Turns Agent Failures Into Verified Training Tasks
On October 2, 2026, ServiceNow CoreAI detailed AutoSynthData on Hugging Face—an open pipeline that mines target-model failures in EnterpriseOps Gym, generates teacher-validated tasks with verifiers, and lifts Gemma Pass@1 by 7.2 points on Hybrid after synthetic SFT.
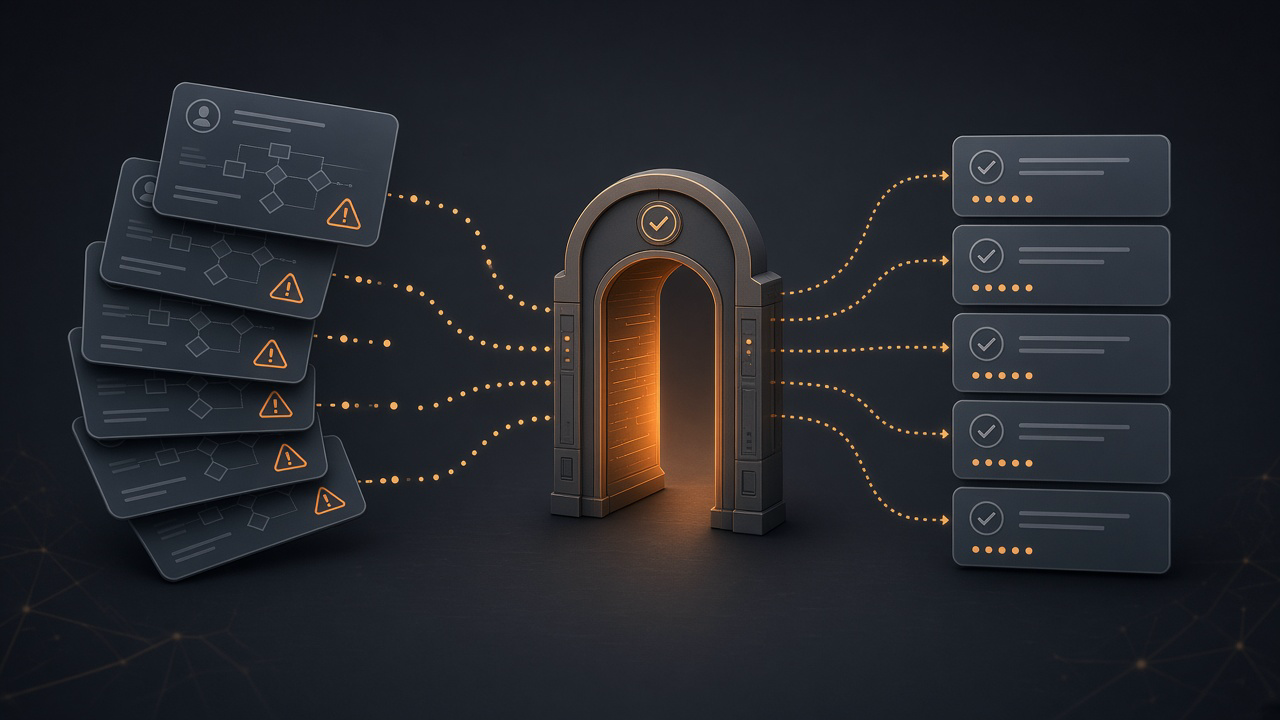
On October 2, 2026, ServiceNow CoreAI published AutoSynthData on the Hugging Face blog—a curriculum-style pipeline that converts an enterprise agent’s measured weaknesses into new, environment-executable training tasks with system specs, user prompts, and verifiers, then uses a stronger teacher’s successful trajectories for supervised fine-tuning. The write-up is grounded in EnterpriseOps Gym (Malay et al., 2026) rather than chatbot chats: agents operate in stateful Hybrid and ITSM worlds where tools, policies, and seeded databases define what “done” means. The problem AutoSynthData attacks is familiar to anyone building internal agents—a capable model still fails specific workflows, tool mixes, or constraints, and a handful of failure logs do not make a post-training set.
What counts as a useful agentic task
ServiceNow’s abstraction is task = (system specification, user prompt, verifier). The system specification covers instructions, policies, and task-specific initialization such as database seeds or knowledge articles; it must stay compatible with the environment’s tools and legal transitions. The user prompt needs feasibility (at least one valid trajectory exists), realism (something a worker would ask), and difficulty (hard for the current target, solvable by a stronger teacher). The verifier must be consistent with those constraints, sound enough to reject bad endings, and complete enough not to demand one brittle golden path. Those three properties matter because a lax verifier rewards wrong behavior in SFT, while an over-narrow verifier punishes valid alternatives.
AutoSynthData first runs diagnostic evaluations of the target and a teacher, then distills sanitized capability-specification cards. Generators never see the original eval prompts, entities, trajectories, or verifier internals—only the cards—so new tasks exercise the same capability with different wording, states, and solution paths.
Target, multiply, and the quality gates
Generation runs in two phases. Target workers create core samples in parallel around those capability cards. Multiply expands accepted targets into novel variants that still pass the same checks; multiplied samples cannot seed further multiplication, which limits drift. A shared controller handles coverage and dataset construction; an environment adapter owns execution, state, reference replay, deterministic verification, and profiling.
Every candidate faces sample-level gates before it enters training. Solver evaluation favors tasks the target solves on at most one of three trials and the teacher solves on at least two of three. Positive verification replays the reference trajectory and checks the verifier. Negative verification mutates expected outcomes to ensure the verifier fails correctly. Failed candidates go through bounded critique-and-repair rather than immediate discard. Batch-level meta-review then watches for overrepresented families, missing capability dimensions, and chronic generation failures, steering the next batch’s budget.
Why enterprise gyms need this loop
Generic instruction datasets rarely encode the stateful quirks of ITSM queues, hybrid tool graphs, or policy gates that block otherwise “correct” actions. AutoSynthData’s contribution is procedural: diagnose gaps from paired target/teacher rollouts, sanitize them into capability cards, generate varied feasible tasks, and refuse to train on candidates that fail execution or verifier soundness. The multiply phase is the scale lever—once a core task is vetted, variants change entities and wording without cloning the eval set. That is a different posture from dumping raw agent traces into SFT and hoping coverage appears.
Hybrid and ITSM results
On EnterpriseOps Gym Hybrid, AutoSynthData used Gemma-4-26B-A4B-it as the target and Qwen3.8-27B as the teacher, producing 2,000 synthetic samples in about 18 hours. Fine-tuning Gemma and picking the best checkpoint (epoch 5) improved mean Pass@1 by 7.2 percentage points—a 35% relative lift—raised verifier success from 63.01% to 68.55%, and closed 59% of the original Pass@1 gap to the reference model. On ITSM, the same target with DeepSeek-V4.1-Flash as teacher yielded 1,994 samples over 66 hours (larger teacher, earlier pipeline); Pass@1 rose from 18.77% to 27.18%. ServiceNow notes the generator never received the original evaluation tasks, so gains reflect newly synthesized work in the same environments.
The roadmap hint is a moving frontier: after each post-training round, re-evaluate, retire tasks the model now owns, and regenerate around remaining gaps—SFT today, with RL as a planned extension. For Writeble’s ai-agents desk, AutoSynthData is the October 2 enterprise recipe that treats synthetic data as searched capability work near the model’s failure boundary, not as undifferentiated prompt spam.
- #AI Agents
- #Synthetic Data
- #ServiceNow
- #EnterpriseOps Gym
- #Post-Training

Author
Raj M
Contributor
AI Systems Architect is a seasoned technology leader with over 15 years of experience in the IT industry working with Fortune 500 companies. With a solid foundation in multi-agent systems, open-source LLM infrastructure, and enterprise deployment, he excels at building scalable production-grade AI platforms.